Table of Contents
SoftBank announced in May 2024 that it was developing AI-assisted voice processing to make an angry caller sound calmer to a call-center worker while preserving the spoken content. The company planned internal and external testing and said it aimed to commercialize the technology by the end of March 2026. That development target should not be described as a confirmed nationwide service launch without a later SoftBank release establishing availability.
What the system is intended to do
The proposed system combines emotion recognition with real-time voice conversion. It analyzes an incoming caller's speech, identifies vocal features associated with agitation, and changes delivery characteristics before the audio reaches the employee.
The aim is to reduce the impact of shouting or an aggressive tone without rewriting the customer's complaint. The agent should still hear the words, names, dates, account details, and requested resolution.
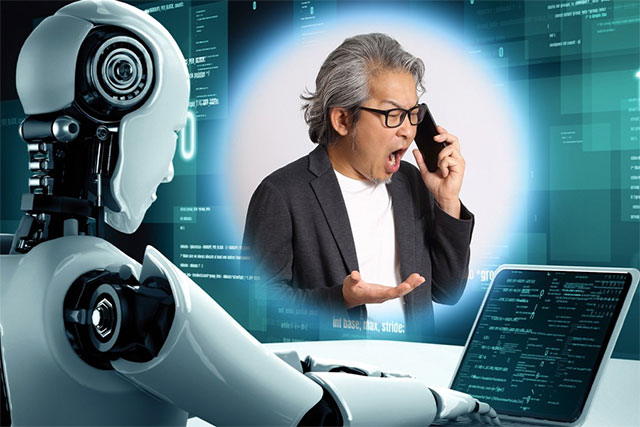
This is different from deleting abusive language, generating a transcript, or replacing a human agent. It is also different from call recording and sentiment scoring, although a commercial deployment could combine several functions.
What SoftBank actually announced
Reuters reported in May 2024 that SoftBank was developing the technology, planned testing over the following year, and targeted commercialization by the end of March 2026. The report described the project as an effort to support worker wellbeing and customer communication.
The original article's claims that the service had launched, was trained on more than 60,000 hours of audio, and reduced employee stress by more than 30% were not supported by the available announcement. Those figures should not be repeated without a primary technical or trial report that defines the dataset, test method, sample, and result.
Why call centers are interested
Call-center staff must solve legitimate problems while controlling their own reaction to anger, threats, insults, and repeated demands. Sustained exposure can increase emotional strain and make it harder to listen accurately. Voice processing could reduce the immediate acoustic intensity while keeping the complaint available for resolution.
The technology is connected to wider concern in Japan about customer harassment, often shortened from the Japanese phrase to kasu-hara. The 2024 Reuters report cited a UA Zensen union survey in which about half of roughly 33,000 respondents said they had experienced customer harassment during the previous two years. That figure describes surveyed workers in particular service and retail contexts; it should not be generalized to every Japanese worker or call center.
Why preserving the words matters
A customer can be angry for a valid reason: an unexpected charge, lost service, safety problem, or unresolved complaint. A system that removes substantive content could prevent the agent from understanding the issue or documenting misconduct.
A responsible design should keep the lexical content intact and make processing visible to both the organization and its workers. It should also retain a controlled way for authorized reviewers to assess the original call when needed for quality, dispute resolution, threats, or legal obligations.
Important limitations
Emotion is difficult to infer from voice
Volume, pitch, rate, and roughness can vary because of language, accent, disability, age, equipment, background noise, stress, or an individual's ordinary speaking style. A classifier may label urgency or cultural speech patterns as anger. Performance should be tested across representative callers and network conditions.
Calmer audio does not remove harassment
Changing tone does not make threats, insults, discriminatory language, or repeated abuse acceptable. Employers still need a harassment policy, supervisor escalation, call-ending rules, incident reporting, and access to worker support.
Processing can change meaning unintentionally
Prosody communicates emphasis, urgency, sarcasm, distress, and uncertainty. Excessive smoothing could make a safety complaint seem routine or hide cues an agent needs. The system should minimize alteration, preserve intelligibility, and allow workers to review or bypass processing under defined conditions.
Latency and audio quality matter
Real-time conversion must operate with low enough delay for natural turn-taking. Telephone compression, overlapping speech, poor microphones, and noisy environments can reduce quality. Organizations should measure dropped words, recognition errors, latency, and agent comprehension—not only whether the result sounds calm.
Privacy, consent, and record keeping
Voice audio can contain personal information and, in some systems, biometric identifiers. Before deployment, an organization should determine:
- What audio, transcript, emotion label, and transformed output are collected.
- Whether callers and employees must be notified or give consent.
- How long original and processed audio are retained.
- Who can replay the original voice and for which purposes.
- Whether data is used to train or evaluate models.
- Where processing occurs and which vendors receive the audio.
- How callers can challenge an incorrect interpretation.
Requirements differ by jurisdiction and use case. Employers should obtain privacy, employment, accessibility, and telecommunications review before processing live calls.
A safer deployment checklist
- Begin with a voluntary pilot. Let a representative group of agents compare processed and unprocessed audio.
- Define the goal. Measure comprehension, fatigue, escalation, and error rates rather than a vague “calmness” score.
- Test diverse calls. Include accents, languages, disabilities, background noise, poor connections, and genuine emergencies.
- Keep human control. Provide a clear way to disable or bypass transformation.
- Separate protection from discipline. Do not use uncertain emotion labels as the sole basis for punishing customers or evaluating employees.
- Preserve escalation paths. Threats and abuse still require supervisor, safety, and incident procedures.
- Audit changes. Compare the original and transformed audio for missing words, shifted emphasis, and unequal performance across groups.
- Communicate honestly. Explain what the system changes, what it records, and what it cannot guarantee.
How to judge whether it helps
A credible evaluation would compare similar call types with and without processing, use enough agents and calls, and define outcomes in advance. Useful measures include listening effort, comprehension errors, call resolution, escalation, worker-reported strain, latency, audio defects, and customer outcomes.
Short demonstrations can show that voice conversion is possible, but they do not establish long-term mental-health benefits or a business return. Any claim of a percentage improvement should identify the sample, control condition, measurement scale, and statistical uncertainty.
The broader lesson
SoftBank's project illustrates a new type of workplace AI: instead of automating the employee's answer, it changes how a stressful input is delivered. That may become a useful protective layer, but it cannot replace staffing, training, breaks, enforcement of conduct rules, and accountable management.
The accurate status from the documented announcement is a technology under development with a stated commercialization target. Confirmed product name, customers, pricing, technical specifications, and measured impact require a later official release or published trial.
Related Articles
 How to Filter Spam Calls on FaceTime: Step-by-Step Guide3 minutes read
 How to Make Free Calls from Computer to Phone4 minutes read
 How to Block Anonymous Calls That Are Harassing You5 minutes read
 Viber Launches Viber Out, Allowing Calls to Any Fixed and Mobile2 minutes read
 How to Block Incoming Calls: Step-by-Step Guide13 minutes read
 Use IFTTT to Not Miss an Important Phone When You Forget to Turn on8 minutes read
Reader Comments 0
Sign in with email or Google to join the discussion.