Table of Contents
An AI agent is ready for production only when it can use trusted data, operate within a clearly bounded workflow, and be monitored against measurable standards. A convincing demo is not enough: real systems contain incomplete records, ambiguous requests, unreliable integrations, permission boundaries, and exceptions that the demo may never encounter.
The following three requirements help teams turn an experiment into a controlled business process. They apply whether the agent was built with code or with one of the common AI agent frameworks.
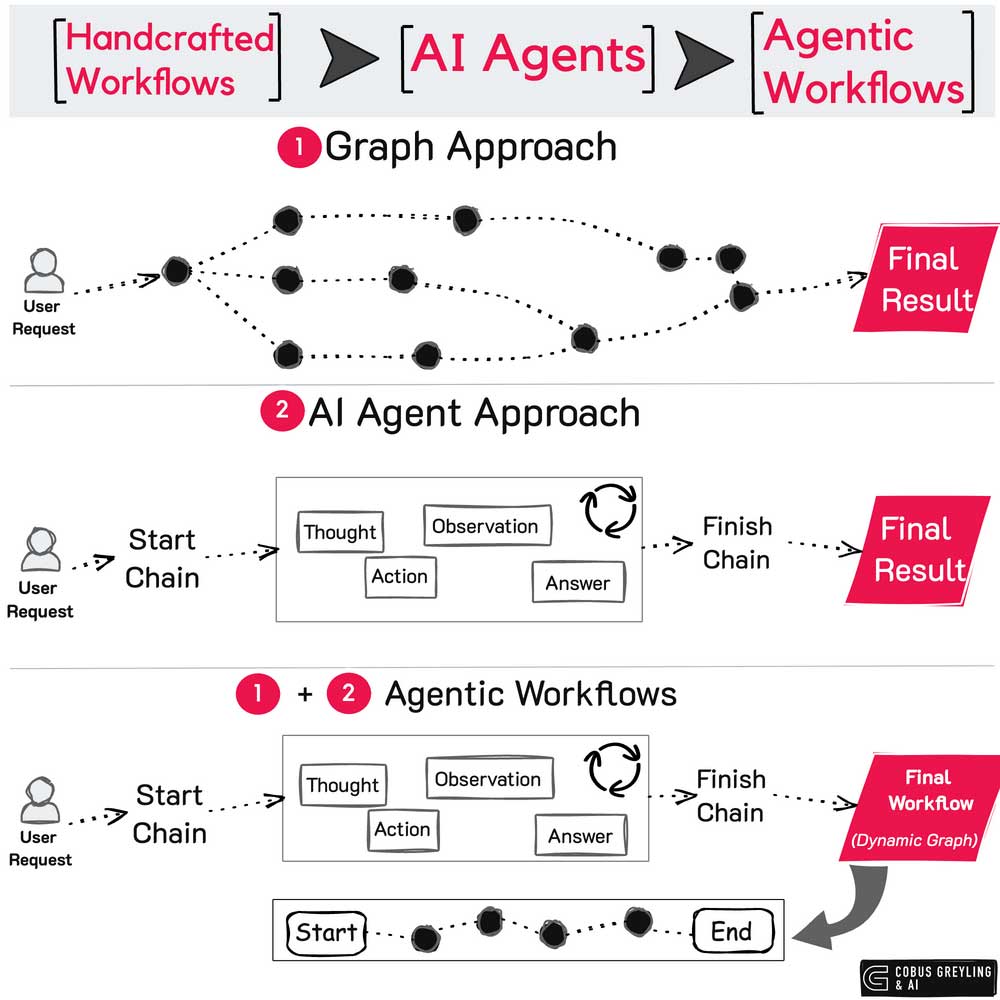
Why an agent that works in a demo can fail in production
A demo usually has clean inputs, a cooperative user, and a narrow happy path. Production adds changing data, concurrent users, tool failures, policy restrictions, and requests that fall outside the intended scope. An agent may also return a plausible-looking answer even when a required system did not respond.
Before rollout, define what success means at the task level. “The agent answered” is not a useful standard. A better definition might require the correct record to be updated, mandatory fields to be present, prohibited actions to be blocked, and uncertain cases to be escalated to a person.
1. Govern the data and tools the agent can use
An enterprise agent often needs information from a CRM, document store, ticketing system, or internal database. The important question is not simply whether it can connect, but whether it can identify the authoritative source, retrieve only permitted data, and handle missing or conflicting records.
- Identify systems of record: document which source is authoritative for each field and how fresh the data must be.
- Use least-privilege access: give the agent only the data and actions required for its assigned task. Separate read access from write or approval privileges.
- Define tool contracts: validate inputs and outputs, set timeouts, and return explicit error states instead of letting a failed call look like success.
- Protect sensitive data: minimize what is sent to a model, apply retention rules, and test that access controls remain effective across connected systems.
A data virtualization layer may help an agent query several systems without copying every record into a new database, but it does not solve ownership, permissions, data quality, or audit requirements by itself.
2. Start with a bounded workflow and clear approval points
The safest first use case is repetitive enough to evaluate, has a recognizable start and finish, and allows mistakes to be caught or reversed. Document checks, ticket classification, draft generation, and renewal reminders can be suitable candidates when their rules and escalation paths are explicit.
For each workflow, specify:
- the inputs the agent may accept and the systems it may call;
- the actions it may take automatically;
- the conditions that require human approval;
- the cases it must reject or escalate;
- the maximum number of retries, steps, or elapsed time; and
- how a mistaken change can be rolled back.
Keep consequential actions—such as sending money, changing access, approving a contract, or releasing regulated information—behind deterministic checks and appropriate human authorization. Adding more agents is not automatically safer or more capable; use a multi-agent design only when the roles, handoffs, and failure modes are easier to evaluate than a single bounded workflow.
3. Evaluate, observe, and govern the agent continuously
Production evaluation should include normal tasks, edge cases, hostile or misleading inputs, unavailable tools, stale data, and permission failures. Build a representative test set and rerun it whenever the model, prompt, tools, retrieval source, or policy changes.
A useful operations dashboard should show more than completion volume. Track:
| Measure | What it reveals |
|---|---|
| Task success rate | Whether the required business outcome was completed correctly |
| Critical error rate | How often the agent causes a prohibited or high-impact failure |
| Escalation rate | How often a person must review or finish the work |
| Latency and cost | Whether the workflow remains practical at production volume |
| Tool and data failures | Which dependencies are creating unreliable results |
Retain audit logs for inputs, tool calls, approvals, outputs, and configuration versions according to the organization’s privacy and retention policies. Assign an owner who can pause the agent, investigate incidents, and approve changes. The NIST AI Risk Management Framework provides a vendor-neutral structure for governing, mapping, measuring, and managing AI risk.
A practical deployment loop
- Set a baseline: measure the current human process, including accuracy, exceptions, time, and cost.
- Test offline: run representative historical or synthetic cases without allowing production actions.
- Use shadow mode: let the agent propose decisions while people continue to perform the real work, then compare outcomes.
- Launch a limited pilot: restrict users, data, permissions, and transaction volume. Keep a documented rollback path.
- Review failures: classify whether each problem came from the model, prompt, data, tool, workflow, or policy.
- Expand gradually: increase autonomy only when measured performance and controls meet the predefined threshold.
Teams evaluating supporting software can also compare AI workflow automation tools, but tool selection should follow the workflow and control requirements—not replace them.
Common deployment mistakes
- Choosing a broad, high-risk process because it looks impressive in a demo.
- Measuring fluent responses instead of completed and verified outcomes.
- Allowing write access before read-only and shadow-mode testing is complete.
- Treating every exception as a prompt problem when the real cause is missing data or a brittle integration.
- Changing models or prompts without rerunning the evaluation set.
- Launching without an accountable owner, incident procedure, or kill switch.
Successful deployment is a systems problem, not just a model-selection problem. Govern the data and tools, constrain the first workflow, and expand autonomy only after evaluation and operational evidence justify it.
Related Articles
 How Real Estate Agents Can Benefit from CRM8 minutes read
 What AI Applications Will Truly Create Value for Businesses in 2026?8 minutes read
 Improper AI Deployment Can Lead to Staffing Crises and Productivity Losses for Businesses6 minutes read
 Overview of Agent Evaluation7 minutes read
 How Will AI Agents Change the Field of Data Science?9 minutes read
 How to Come up with an Ideal and Functional Website for Real7 minutes read
Reader Comments 0
Sign in with email or Google to join the discussion.