Table of Contents
Few-shot prompting means placing a small set of example inputs and desired outputs in a prompt before giving the real task. It is useful when a written instruction leaves room for interpretation, especially for classification, extraction, formatting, and tone.
Examples can make results more consistent, but they do not train the underlying model or guarantee accuracy. Treat them as part of the current prompt, test the result on cases the model has not seen, and verify high-impact outputs.
Zero-shot, one-shot, and few-shot prompts
- Zero-shot: instructions without an example.
- One-shot: one example of the desired input-output relationship.
- Few-shot: several examples that demonstrate the pattern and its boundaries.
A zero-shot sentiment prompt might say:
Classify the customer message as Positive, Negative, Neutral, or Mixed.
Message: "The product works well, but delivery was two weeks late."
Return only the label.
A few-shot version makes each label and the required format visible:
Classify each message as Positive, Negative, Neutral, or Mixed.

Message: "The setup was simple and everything works."
Label: Positive

Message: "It arrived broken and support has not replied."
Label: Negative

Message: "The package arrived on Tuesday."
Label: Neutral

Message: "The product works well, but delivery was two weeks late."
Label: Mixed

Now classify:
Message: "The design is excellent, although the battery drains quickly."
Label:
The examples tell the model which labels are allowed, what counts as a mixed case, and how to format the answer.
Choose examples that teach the real task
Use representative inputs
Examples should resemble the language, length, and ambiguity of the data you will process. A placeholder such as “test message here” teaches little about customer requests.
Input: "I placed order 4521 last week, but its status still says pending."
Output: Category: Order status | Reference: 4521 | Priority: Normal
Cover meaningful variation
Include common cases and the boundaries that matter. For an extraction task, show a complete record, a missing field, and an ambiguous value. For classification, cover each permitted label rather than repeating the easiest class.
Keep the structure consistent
Use the same field names and order in every example. If one answer uses JSON, another uses prose, and a third uses a table, the target format becomes unclear.
Do not invent policy through an example
An example is also an instruction. A sample customer reply that promises a refund or delivery date may cause the model to repeat that commitment. Use only approved facts and policies, and mark missing information explicitly.
How many examples should you use?
| Starting point | When it can help |
|---|---|
| One example | A simple format with little ambiguity |
| Several examples | Multiple labels, edge cases, or a specific voice |
| More examples | Only when each one teaches a distinct rule or boundary |
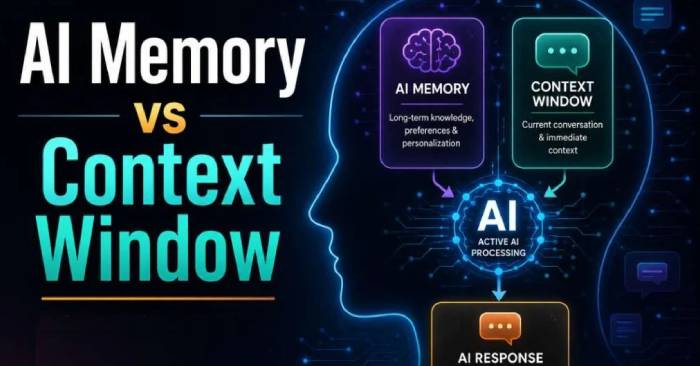
There is no universal best number. Add an example when it resolves a real failure; remove it when it repeats the same pattern or consumes space without improving results. The guide to AI context and few-shot examples explains why prompt space and memory are separate concerns.
A reusable few-shot template
Task: [Describe the task and its purpose.]
Allowed outputs: [List labels or define the schema.]
Rules:
- [Important constraint]
- If a required fact is missing, write "Not stated."
- Do not infer details that are absent from the input.

Examples:
<example>
Input: [Representative input 1]
Output: [Correct output 1]
</example>

<example>
Input: [Representative input 2 or edge case]
Output: [Correct output 2]
</example>

Actual task:
Input: [New input]
Output:
Clear separators reduce the chance that the model confuses an example with the real request. The exact tags are optional; consistent structure matters more. Anthropic's prompting guidance likewise recommends relevant, varied, and clearly structured examples.
Example: classify product titles
Task: Assign each product to exactly one approved department.
Departments: Electronics; Home & Kitchen; Clothing; Sports & Outdoors; Books; Toys & Games.
Return only the department name.

Product: "Instant Pot Duo 7-in-1 electric pressure cooker"
Department: Home & Kitchen

Product: "Nike Revolution men's running shoes"
Department: Clothing

Product: "Kindle Paperwhite 16 GB e-reader"
Department: Electronics

Product: "LEGO Star Wars Millennium Falcon building set"
Department: Toys & Games

Product: "Sony WH-1000XM5 wireless noise-cancelling headphones"
Department:
The approved list prevents the model from creating an extra label such as “Audio.” If the business uses a different taxonomy, replace both the list and examples with its actual categories.
Example: demonstrate tone without copying wording
For a writing task, examples can demonstrate sentence length, level of formality, and how the reply moves toward a solution. Remove names and confidential details before sharing samples.
Write a concise customer-support reply. Acknowledge the issue, state only confirmed facts, and ask for the information needed for the next step.

Customer: "My order still shows pending."
Reply: "I understand why the delay is concerning. I can check the status once you share the order number."

Customer: "The item stopped working after one day."
Reply: "That should not have happened. Please send the order number and a photo of the issue so the support team can review the available resolution."

Customer: "Can I change the delivery address?"
Reply:
Review the generated reply for commitments that were not in the brief. Examples can steer tone, but they should not substitute for current policies or human approval.
Test and improve the prompt
- Create a small test set that is separate from the examples.
- Define what counts as correct: label, fields, format, factual fidelity, or tone.
- Run the same prompt on ordinary and difficult cases.
- Record the failures. Change the instruction or add one targeted example that addresses a repeated failure.
- Retest the original cases to make sure the change did not create a new problem.
Common causes of weak results include examples that contradict one another, examples that do not resemble real inputs, and outputs containing facts the model could only guess. For a broader prompt framework, see how to build a complete prompt and the basic prompt structure.
Related Articles
 AI Memory, Context Windows, and Few-Shot Examples7 minutes read
 What Is Deepfake?3 minutes read
 5 Surprising Disadvantages of Using the Pomodor Technique5 minutes read
 How to Turn Off the 'Shot on Dual Camera' Logo on Xiaomi Phones5 minutes read
 New Hacking Technique: Complete Guide3 minutes read
 What Is the Clean Room Technique?3 minutes read
Reader Comments 0
Sign in with email or Google to join the discussion.